In recent years, Machine Learning (ML), Artificial Intelligence (AI), Deep Learning are topics that are driving electronic device development.
ML and AI are starving for computational power.
FPGAs, mainly modern ones, are used in ML/AI since they can implement a lot of convolutional engines inside due to the intrinsic parallel architecture.
The CPUs and GPUs are processing units that can have (especially GPU) a lot of computational general-purpose engines inside.
A CNN kernel is basically a matrix multiplication. The faster a device can perform such multiplication, the faster the device can “think”. This is an intrinsic parallel architecture so which is the best device that can be used to implement such architecture?
Yes, the FPGA!
The modern FPGA implements a lot (in the order of thousands) Multiply and Accumulate (MAC) engines inside.
For instance, high-end FPGA such as the Kintex UltraScale KU13P has 3528 MACs inside or the Virtex Ultrascale up to 12288 MACs.
The Intel Stratix MX 2100 implements 7920 MACs or in the Intel DX 2800, there are 11520 MACs inside!
Well, a lot of stuff…
Think about how many multiplications you can perform for each clock cycle!
No GPU can win against such computational power!
But… the power is nothing without control!
First of all, if you want to take advantage of such MACs you need to understand Digital Signal Processing (DSP).
As you can see in the FPGA datasheet, all these devices are optimized to handle fixed-point numbers.
Ok, in the modern FPGA you can also use floating-point representation, but you are wasting a lot of processing (and dissipation) power without taking real advantage from these devices!
Well, let’s understand how to implement a CNN kernel.
CNN Kernel implementation
The first thing to do when working with CNNs is to quantize the network coefficients. Generally, we can use INT8 quantization. I mean 8-bit quantization both for the weights and the input to the network. The modern FPGA can handle 2 or more multiplications per single MAC engine. In this case, the number of MACs above can be doubled!
A typical convolutional kernel is:
where N = 3 or 5 or more.
This is a typical matrix multiplication.
We can implement such a kernel in different ways, depending on how fast we want to compute the result.
I mean, we can use a single MAC and compute the output after M clock cycles where M=N*N
If we parallelize the operations, we can reach a real-time computation, I mean, one output per clock cycle.
Of course, the implementation depends on the data rate we need to guarantee and on how many MACs are available on our FPGA.
CNN Kernel as FIR Filter
Let’s see a CNN kernel implementation for N=3.
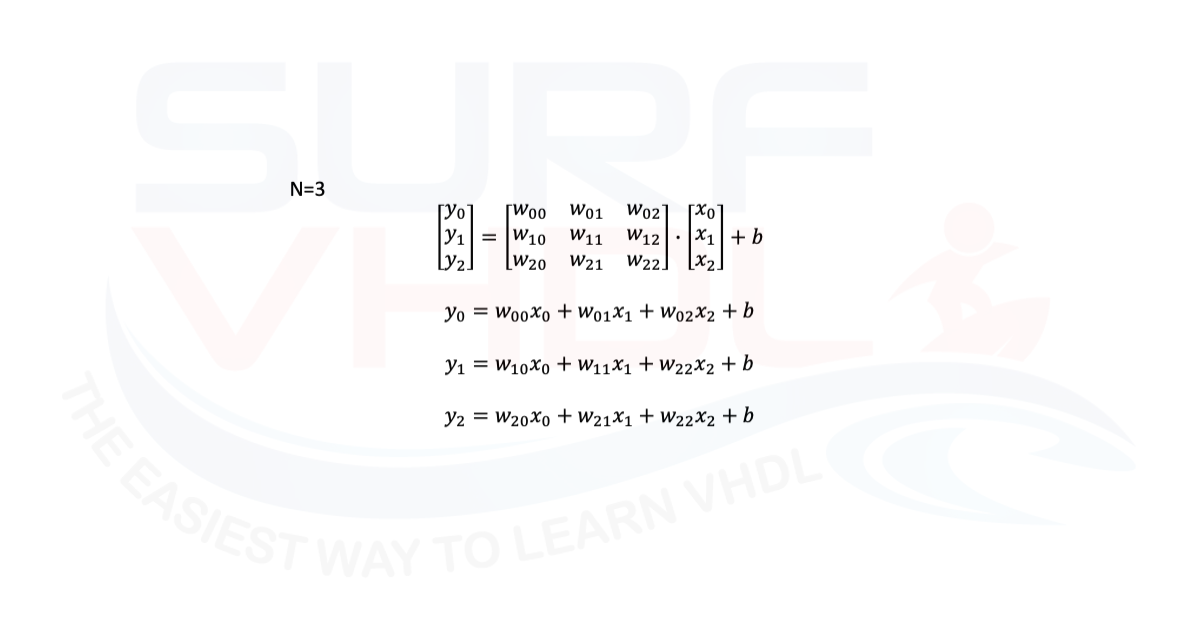
As you can see, we can implement the matrix multiplication as 3 FIRs of three taps per filter. On the other hand, we can see a FIR as scalar product of two vectors:
coefficient vector by data pipe vector.
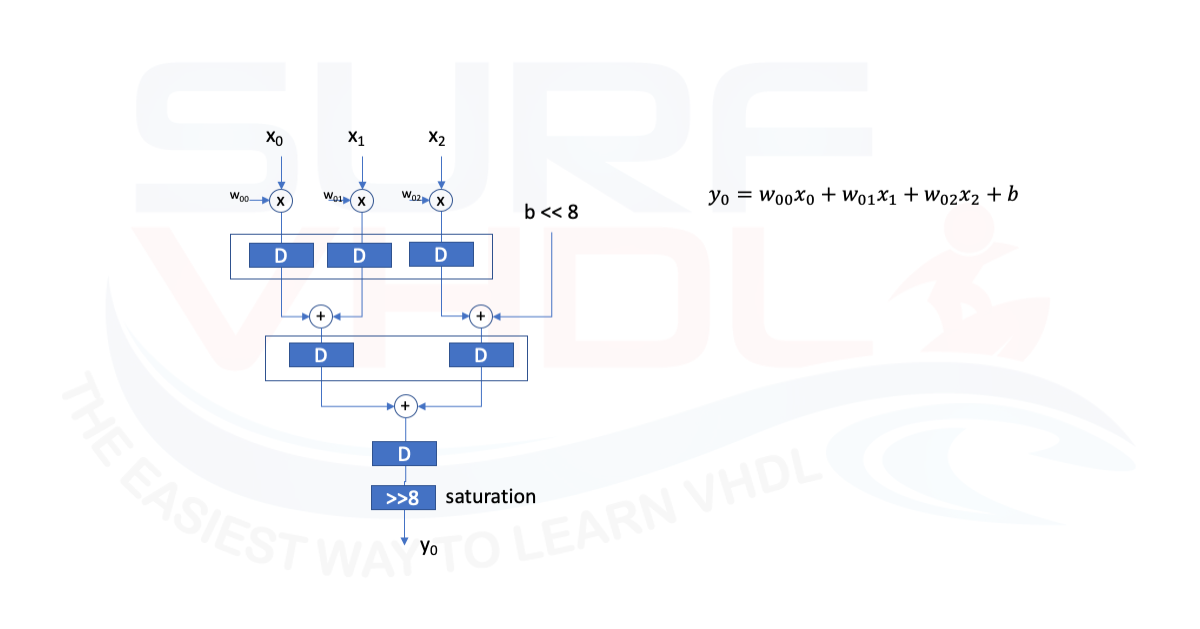
In this example, what is missing is the output section of a CNN kernel: the activation function.
The activation function can be easily implemented as a LUT. You can see an example in this post.
Now, we know how to implement a FIR filter.
If not, just take a look at this post.
Bit-width Management
As stated before, we will use INT8 quantization, I mean, the coefficients and inputs are 8 bits wide.
The internal operations are computed at full dynamic, in this example, the output will be the 8 MSB of the full dynamic operation.
When we multiply two numbers NxM the result is N+M bit. In this case input and coefficient are 8 bit, so the result will be 16 bits.
So if we want to add the constant b at this stage, we need to take into account the increment of the dynamic due to the multiplication operation, in this case, 8 bit due to the coefficient w.
Then we have the increment of dynamic due to the addition operation.
Even in this case we need to cut the output dynamic to 8 bits. We will use the same strategy used for the FIR implementation. I mean we will shift by a certain number of bits and then saturate at 8 bits.
The number of right shifts depends on the coefficient value and input value. This is a very delicate point and requires simulation at system level.
You can perform some MATLAB simulations to understand the optimum amount of shift you need to perform. In this example we can assume a shift by 8 and then saturation.
Conclusion
As you can see, a CNN kernel can be seen as a simple FIR implementation with some optimization. You can find a VHDL example of such CNN kernel here.
References
[1] Intel STRATIX 10
[2] Xilinx VIRTEX and Kintex Ultrascale
[3] Wikipedia CNN
[5] Icons made by Freepik from www.flaticon.com